
I keep seeing the same conclusion in local AI evaluations: the model loaded, the prompt completed, and therefore the device is considered a good fit.
I do not believe that is enough.
A customer does not buy a specification sheet and experience a parameter count. The customer experiences a wait, an answer, and an outcome. If a model technically runs but takes twelve minutes to return an answer, misunderstands the instruction, or confidently invents the facts, the technology may be functioning while the experience is failing.
Works well is a customer verdict.
The benchmark and the experience are drifting apart
Traditional hardware benchmarking is good at measuring isolated performance. It can tell me how quickly a system generates tokens, how much memory is consumed, and whether a model fits within a device's resources.
Those measurements are necessary. They are not sufficient.
Tokens per second, or TPS, is like measuring a restaurant by how quickly plates leave the kitchen. Speed matters, but it tells me nothing about whether the order was correct, the food was edible, or the customer received the meal in time to enjoy it.
The industry is already moving toward a broader view. MLCommons separates time to first token, or TTFT, from the speed of subsequent token generation. Its client benchmarking work is scenario-driven and grounded in end-user use cases. Stanford's Holistic Evaluation of Language Models, known as HELM, measures multiple dimensions including accuracy, robustness, fairness, toxicity, and efficiency across representative scenarios.
This evidence points in one direction: an AI experience must be evaluated as a system, not as a model running alone.
A simple customer test
My sales increased 30%, but profit dropped 15%. What are the most likely reasons, and what should I investigate first?
On one hardware configuration, the model answers after six minutes. The response is vague, misses the relationship between revenue and margin, and invents details that were never provided.
On another configuration, the same model starts responding quickly. It explains plausible causes such as discounting, product mix, higher fulfillment costs, returns, or customer-acquisition expense. It clearly separates known facts from hypotheses and proposes the next data to inspect.
The model name is identical. The customer outcome is not.
The second system did more than generate tokens faster. It preserved enough memory and compute headroom to process the prompt, reason over the numbers, follow the requested structure, and return a useful answer within the customer's patience window.
That is why I would never certify an LLM-to-hardware fit from TPS alone.
What customers actually experience
I organize the evaluation into four layers. Each layer answers a different question.
Feasibility
Can it remain stable?
Load time, peak memory, memory headroom, thermals, power behavior, and failures.
Responsiveness
Does it feel alive?
TTFT, token speed, time between tokens, and total completion time.
Quality
Can I use the answer?
Accuracy, reasoning, problem solving, math, completeness, and hallucinations.
Workflow
Did it finish my job?
Scenario success, retries, corrections, useful output, and time saved.
Feasibility: Can it load and remain stable?
Memory headroom matters because an LLM needs more than its stored weights. It also needs working memory for the prompt, generated output, software runtime, and the KV cache. The KV cache is like the notes an assistant keeps while reading a long meeting transcript. The longer the conversation, the larger that notebook becomes.
Responsiveness: Does it feel alive?
TTFT is the pause between asking a question and seeing the first sign of life. A model can have strong average TPS and still leave the customer staring at a blank screen while a long prompt is processed. That is why TTFT and end-to-end completion time must sit beside TPS.
MLPerf has used human experience as an anchor for latency. Its Llama 2 70B benchmark described TTFT and time per output token as separate constraints, while later MLPerf work reported that roughly 20–50 generated tokens per second can support a seamless interactive experience. These are useful reference points, but the acceptable target still depends on the task. A short chat and a ten-page report are not the same workload.
Quality: Is the answer correct and useful?
A hallucination is like a confident employee filling a missing spreadsheet cell with a guess and presenting it as audited data. Fluency can hide the error. That is why polished language cannot be treated as proof of quality.
Different tasks need different scoring. A math problem can use an exact answer. A structured request can verify valid JSON and required fields. A summary can be checked for coverage, faithfulness, and unsupported claims. A business recommendation may need both a rubric and informed human review.
Workflow: Does it complete the customer's real job?
I run repeatable scenarios using realistic prompt lengths, files, output expectations, and follow-up questions: summarizing a ten-page report, comparing proposals, explaining a business result without inventing facts, turning meeting notes into actions, or following a multi-step instruction.
This is the final test because customers do not wake up wanting 32 tokens per second. They want the report understood, the decision clarified, or the work completed.
MoE can help—but it is not magic
I believe Mixture-of-Experts, or MoE, is an important direction for consumer, gaming, and commercial devices.
The simplest analogy is a hospital with many specialized doctors. When a patient arrives, a coordinator first understands the need and routes that patient to one or two relevant specialists. The hospital does not assign every doctor to every patient.
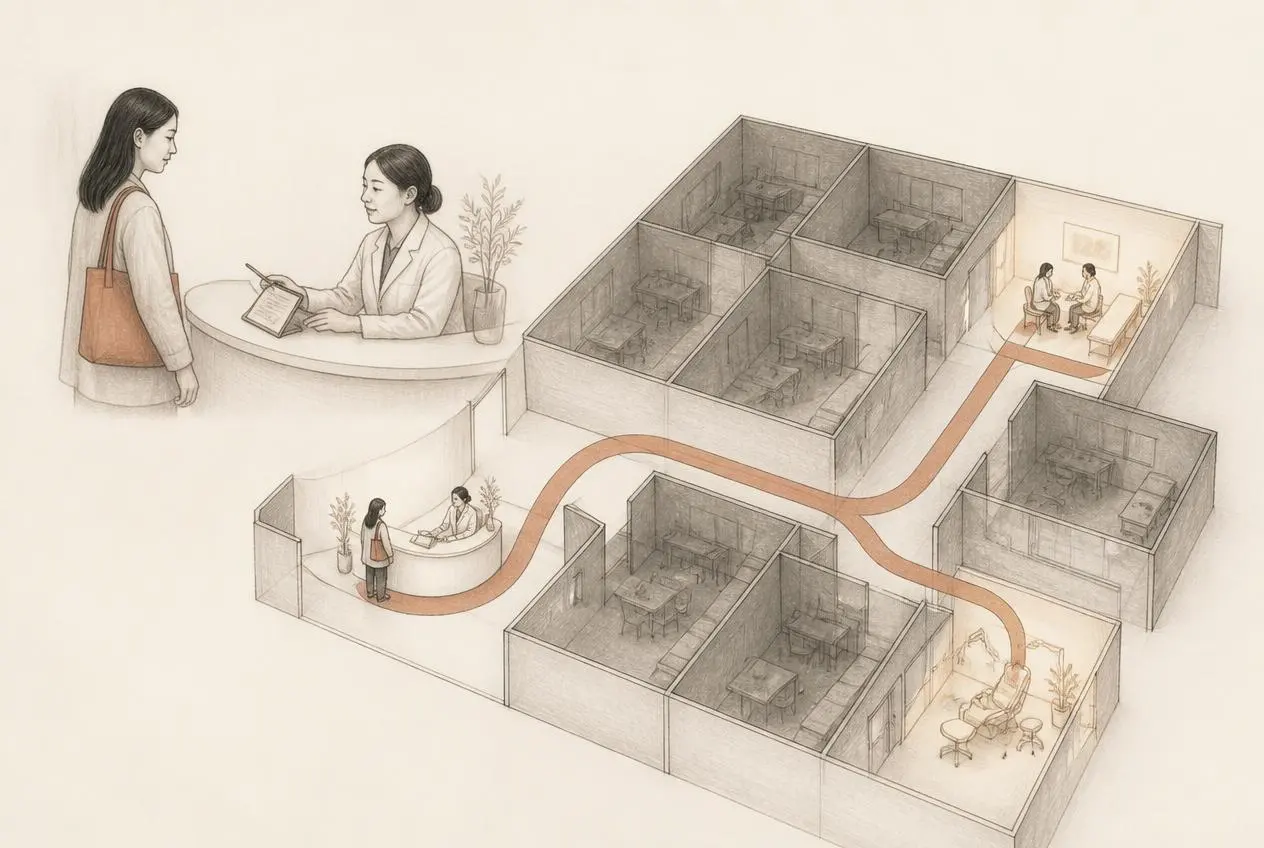
An MoE model works in a similar way. A router selects only a small subset of expert blocks for each token. The well-known Mixtral 8x7B research model, for example, has about 47 billion total parameters but uses about 13 billion active parameters for a token. A hypothetical 120B MoE model might be described as 120B total with 15B active, but that ratio must be verified for the specific model—it is not a rule for every 120B model.
This sparse activation can reduce the compute required for each token and allow more capability than a dense model with a similar active parameter count. But there is an important catch: active parameters are not the same as resident parameters.
The full collection of experts still exists. Depending on quantization, memory architecture, offloading, context length, and serving software, the system may still need to store or move a much larger set of weights. It is like a hospital needing offices and records for all 60 doctors even though only two are seeing the current patient.
My proposed minimum scorecard
| Dimension | Minimum measures | Customer question |
|---|---|---|
| Fit and stability | Load success, memory, headroom, thermals, failures | Will it run reliably? |
| Responsiveness | TTFT, TPS, inter-token latency, total time | How long until a useful answer? |
| Quality | Accuracy, reasoning, math, hallucination rate | Can I trust and use it? |
| Instruction execution | Following, structure, completeness | Did it do what I asked? |
| Real workflow | Success, retries, correction, time saved | Did it complete the job? |
I would also report distribution, not only averages. The 50th-percentile result describes a typical run; the 95th percentile exposes the bad day a customer will eventually experience. I would repeat tests, control model settings, keep prompts identical, and record the entire path from submit to usable result.
Most importantly, I would never collapse everything into one unexplained score. A single score can help leaders compare systems, but the components must remain visible. A fast but inaccurate system and a slow but accurate system fail in different ways and require different decisions.
A more honest definition of “works”
The purpose of a benchmark is not to make hardware look capable. It is to make the customer experience predictable.
A local AI solution works when it completes a representative customer task, within an acceptable time, with a correct and useful result, on the target device, repeatedly.
That definition connects silicon, memory, software, model architecture, and experience engineering. Instead of debating whether a 50B model fits, I can ask a better question: which model, runtime, quantization, and hardware configuration completes the target customer workflow at the required quality and response time?
Model size will continue to matter. TPS will continue to matter. Hardware compatibility will continue to matter. But none of them, alone, tells me whether the product delivers value.
The final benchmark belongs to the customer.
Takeaways
What I keep
- Can run is not the same as works well. Technical execution is only the first gate.
- TPS is one signal, not the verdict. TTFT, total time, quality, reliability, and workflow success complete the picture.
- Real scenarios expose real failures. Benchmark the job customers need to finish.
- MoE is promising, with conditions. Sparse activation helps, while total weights and memory behavior still matter.
- The outcome must be repeatable. A useful answer once is a demo; consistency makes it a product experience.